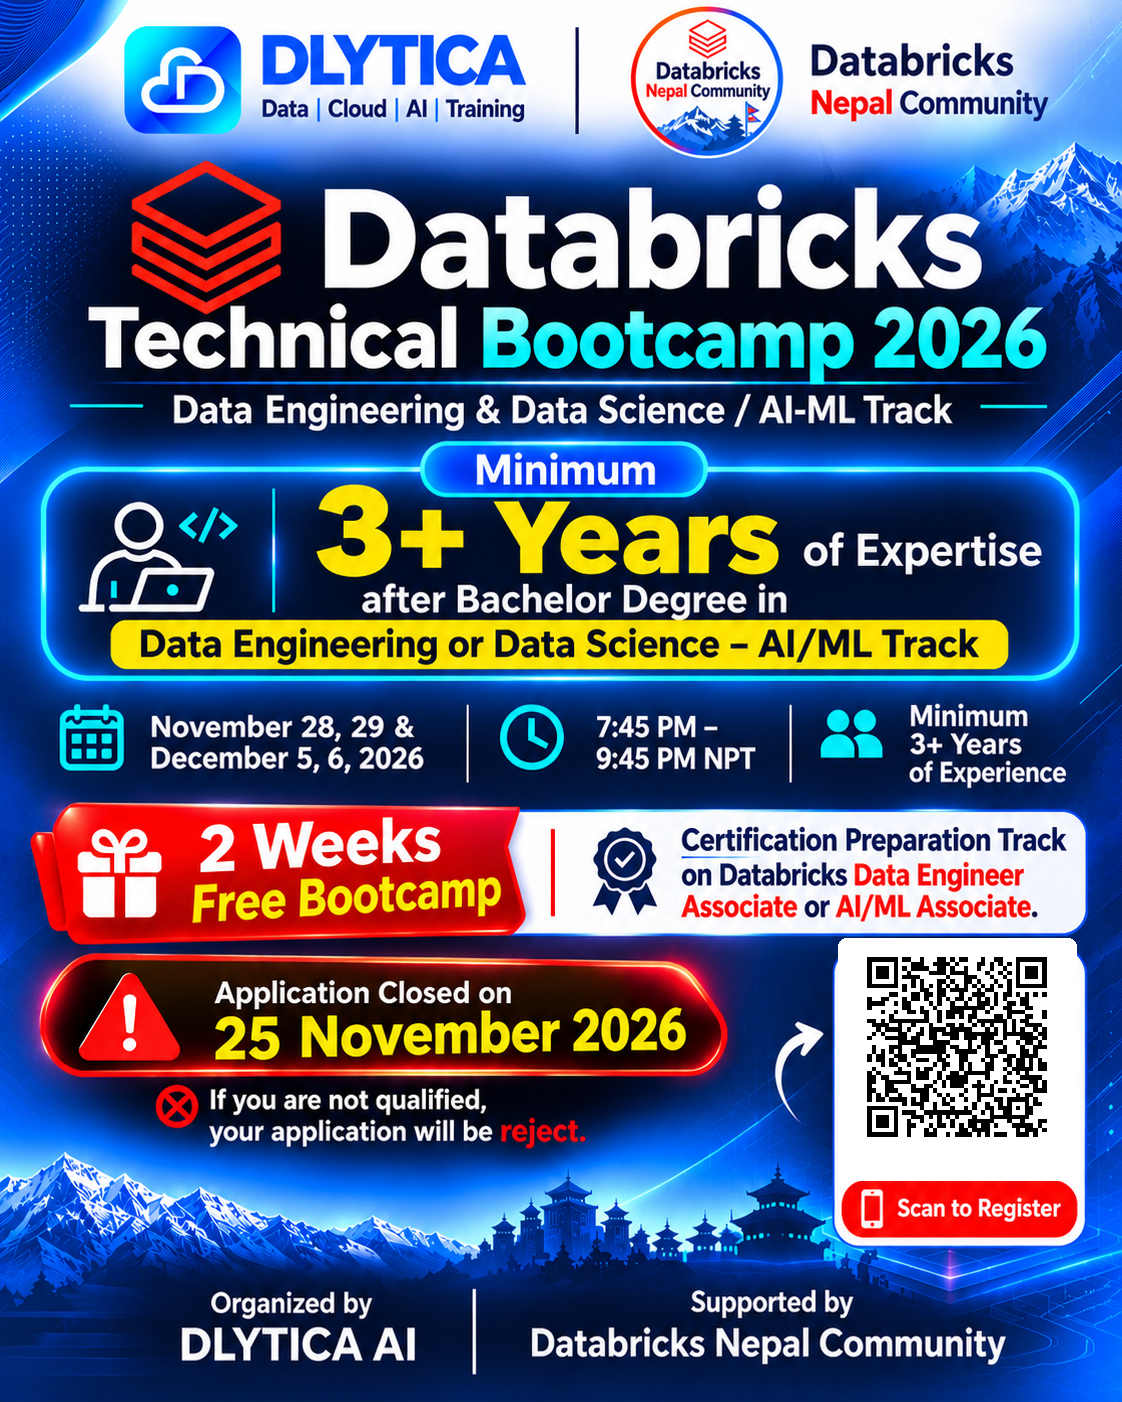
Databricks Technical Bootcamp 2026
November 28, 2026 Online (Join From Anywhere)
Data Engineering & Data Science / AI-ML Tracks
2-Week Advanced Databricks Technical Bootcamp 2026
Build. Optimize. Deploy. Master Databricks.
Organized by Dlytica AI | Supported by Databricks Nepal Community
Take your Databricks expertise to the next level through an intensive, instructor-led technical bootcamp designed for experienced Data Engineers, Data Scientists, Machine Learning Engineers, and AI/ML professionals.
This two-week bootcamp focuses on practical implementation, advanced Databricks concepts, real-world technical challenges, production-ready workflows, Generative AI, and technical interview preparation.
Whether you are building scalable data pipelines or developing production-ready machine learning and Generative AI solutions, this bootcamp will help strengthen your technical capabilities.
Bootcamp overview
| Program | 2-Week Advanced Databricks Technical Bootcamp 2026 |
|---|---|
| Dates | November 28, 29 & December 5, 6, 2026 |
| Time | 7:45 PM – 9:45 PM NPT |
| Duration | 2 Weeks |
| Total Contact Hours | 8 Hours |
| Sessions | 4 Sessions × 2 Hours |
| Format | Online, instructor-led |
| Experience Requirement | Minimum 3+ years |
| Technical Tracks | Data Engineering & Data Science / AI-ML |
| Final Activity | Project Presentations & Evaluation |
| Organized by | Dlytica AI |
| Supported by | Databricks Nepal Community |
Important: Both tracks will have separate classes and technical activities. Participants must select only one track during registration.
Technical tracks
Track One: Modern Data Engineering with Databricks
Theme: Build, Optimize and Manage Production-Ready Data Pipelines
Target audience: Data Engineers and experienced data professionals with a minimum of 3+ years of relevant professional experience.
Instructors: Gaurav Thagunna, Sudip Shrestha
Program objective: Develop practical skills in Databricks architecture, Apache Spark, Delta Lake, incremental data processing, pipeline orchestration, performance optimization, governance, and production deployment.
Topics covered
- Databricks Architecture & Apache Spark Internals
- Lakehouse architecture and platform fundamentals.
- Databricks workspace, compute and Unity Catalog.
- Apache Spark architecture and execution model.
- Driver, Executors, Jobs, Stages and Tasks.
- How Spark executes queries within Databricks.
- Spark Execution, Optimization & Performance Tuning
- Transformations, actions and lazy evaluation.
- Logical and physical execution plans.
- Joins, shuffles, partitioning and data skew.
- Broadcast joins and query optimization.
- Spark UI and performance troubleshooting.
- Delta Lake & Incremental Data Processing
- Delta Lake fundamentals and transaction logs.
- ACID transactions and time travel.
- Schema enforcement and schema evolution.
- Auto Loader and incremental ingestion.
- MERGE INTO and Change Data Feed.
- Slowly Changing Dimensions (SCD Type 1 and Type 2).
- Data Pipeline Development & Orchestration
- Medallion Architecture: Bronze, Silver and Gold.
- PySpark pipeline development.
- Data cleansing, deduplication and transformations.
- Lakeflow Jobs and workflow orchestration.
- Task dependencies, scheduling, retries and monitoring.
- Pipeline failure handling and recovery.
- Performance Optimization, Governance & Cost Management
- OPTIMIZE, Z-ORDER and Liquid Clustering.
- Photon and Adaptive Query Execution (AQE).
- Small-file optimization.
- Cluster sizing, autoscaling and cost management.
- Unity Catalog permissions and access control.
- Data lineage, auditing and governance.
- CI/CD, Hands-on Project & Interview Preparation
- CI/CD and Declarative Automation Bundles (DABs).
- Development-to-production deployment concepts.
- Real-world troubleshooting scenarios.
- End-to-end Retail Customer Analytics Pipeline.
- Databricks Data Engineer Associate certification preparation.
- Technical interview questions and mock discussions.
Expected learning outcomes
- Understand Databricks architecture and Spark execution.
- Develop incremental data pipelines using Delta Lake.
- Build and orchestrate Bronze, Silver and Gold workflows.
- Identify and resolve performance bottlenecks.
- Apply governance and access controls through Unity Catalog.
- Understand production deployment and CI/CD fundamentals.
- Prepare for Databricks technical interviews and certification.
Prerequisites
- Minimum 3+ years of relevant professional experience.
- Basic to intermediate SQL and Python knowledge.
- Understanding of Apache Spark concepts.
- Experience with data processing and data engineering fundamentals.
- Basic Databricks exposure is recommended.
Hands-on project
- Build an end-to-end data pipeline.
- Work with Delta Lake and incremental processing.
- Apply optimization and governance concepts.
- Demonstrate the completed pipeline.
Track Two: Data Science & AI/ML with Databricks
Theme: Build, Evaluate and Manage Machine Learning Solutions on Databricks
Target audience: Data Scientists, Machine Learning Engineers, AI Engineers and AI/ML professionals with a minimum of 3+ years of relevant professional experience.
Instructors: Chhabi Tamang, Keshav Shrestha
Program objective: Develop practical knowledge of the Databricks Machine Learning ecosystem, model development, experiment tracking, model lifecycle management, Generative AI, and AI Agents.
Topics covered
- Databricks Lakehouse & ML Fundamentals
- Databricks architecture and ML workspace.
- Lakehouse fundamentals for machine learning.
- End-to-end machine learning workflows.
- Working with data and ML environments on Databricks.
- Data Preparation & Feature Engineering
- Data exploration using PySpark and Delta tables.
- Data cleaning and preprocessing.
- Data transformations and feature engineering.
- Preparing datasets for model development.
- Model Development & MLflow
- Machine learning model development and training.
- Experiment tracking using MLflow.
- Parameter logging and metrics tracking.
- Model evaluation and performance measurement.
- Hyperparameter tuning fundamentals.
- Model Lifecycle & Production Readiness
- MLflow Model Registry and model versioning.
- Model lifecycle management.
- Unity Catalog governance and access control.
- Model deployment and serving concepts.
- Production-oriented ML workflows.
- Generative AI & AI Agents on Databricks
- Introduction to Generative AI workflows.
- LLM application development concepts.
- AI Agents and agentic AI workflows.
- MLflow evaluation concepts for AI applications.
- Evaluating and managing AI/ML solutions.
- Hands-on Labs, Project & Interview Preparation
- Practical end-to-end machine learning workflow.
- Real-world technical troubleshooting.
- MLflow experiment tracking and model evaluation.
- Databricks Machine Learning Associate certification preparation.
- Technical interview questions and discussions.
- Project presentation and evaluation.
Expected learning outcomes
- Prepare and transform data for machine learning.
- Develop and evaluate machine learning models.
- Track experiments and manage models using MLflow.
- Understand model lifecycle and production readiness.
- Apply Unity Catalog governance concepts.
- Understand Generative AI and AI Agent workflows.
- Prepare for Databricks certification and technical interviews.
Prerequisites
- Minimum 3+ years of relevant professional experience.
- Python and SQL knowledge.
- Foundational machine learning knowledge.
- Understanding of model development and evaluation.
- Familiarity with AI/ML concepts is recommended.
Hands-on project
- Develop and evaluate a machine learning workflow.
- Apply MLflow experiment tracking.
- Explore model lifecycle and Generative AI concepts.
- Present the completed project or practical implementation.
Bootcamp schedule
The bootcamp will be delivered over two consecutive weekends, with four instructor-led sessions.
| Date | Day | Time (NPT) | Activity |
|---|---|---|---|
| November 28, 2026 | Saturday | 7:45–9:45 PM | Session 1 |
| November 29, 2026 | Sunday | 7:45–9:45 PM | Session 2 |
| December 5, 2026 | Saturday | 7:45–9:45 PM | Session 3 |
| December 6, 2026 | Sunday | 7:45–9:45 PM | Session 4 & Project Presentations |
Total Duration: 8 hours of instructor-led technical sessions across two weeks. Both tracks will follow separate class schedules and learning activities.
Who should apply?
- Data Engineers
- Senior Data Engineers
- Data Scientists
- Machine Learning Engineers
- AI Engineers
- AI/ML Professionals
This is an advanced professional learning opportunity, not a beginner-level training program. Minimum 3+ years of relevant professional experience for both tracks.
What will you gain?
- Advanced practical exposure to Databricks technologies.
- Hands-on experience with real-world technical scenarios.
- Better understanding of production-ready data and AI/ML solutions.
- Knowledge of performance optimization and governance.
- Databricks certification preparation guidance.
- Technical interview preparation and practical discussions.
- Experience presenting and explaining your technical work.
- An opportunity to connect with the Databricks professional community.
Registration & selection
To maintain a focused and technically strong learning environment, all applications will undergo a screening and selection process.
How to apply
- Complete the online registration form.
- Select your preferred track: Modern Data Engineering with Databricks, or Data Science & AI/ML with Databricks.
- Provide your professional experience, current role and technical background.
- Submit your application for review.
- Shortlisted candidates will receive confirmation and their respective class meeting links.
Important registration information
- One common registration form will be used for both tracks.
- Applicants must select only one technical track.
- Minimum 3+ years of relevant professional experience is mandatory.
- All applications will be reviewed against the eligibility criteria.
- Registration does not guarantee selection.
- Only shortlisted candidates will receive the online meeting links.
- Meeting links will be shared after the screening and selection process.
- Selected participants are expected to attend all sessions and complete the assigned practical activities.
Take your Databricks expertise to the next level!
The demand for skilled Data Engineers, Data Scientists and AI/ML professionals continues to grow.
Strengthen your technical foundation, explore advanced Databricks capabilities, and gain practical insights from experienced industry professionals.
Whether your focus is scalable data engineering or production-ready AI/ML solutions, this bootcamp is designed to help you move forward.
Minimum 3+ Years of Experience | Limited Seats | Screening Required
Join the Databricks Nepal community
Apply for the Bootcamp
One form for both tracks — pick one. Minimum 3+ years of experience, screening required.
